BlogIT Asset Management Services: The Enterprise Guide to Eliminating Shadow IT and License Waste

Read More

IT Asset Management (ITAM) is a structured approach to tracking, managing, and optimizing an organization’s hardware, software, licenses, SaaS applications, and other technology assets throughout their lifecycle. IT asset management services give IT teams greater visibility into technology usage, ownership, costs, and risks. An effective ITAM strategy helps improve shadow IT visibility across enterprise environments, optimize software licenses, strengthen security and compliance, and support better IT spending decisions.

Modern enterprises manage a growing mix of laptops, servers, mobile devices, software applications, SaaS subscriptions, cloud resources, and network infrastructure. As technology estates become more distributed, keeping track of every asset, its owner, location, usage, cost, and lifecycle status becomes increasingly complex.

This is where IT asset management services help. IT Asset Management (ITAM) provides a structured way to discover, track, manage, optimize, and retire technology assets throughout their lifecycle. With accurate asset data and automated processes, organizations can improve technology visibility, control software spending, reduce Shadow IT risks, and make more informed IT decisions.

This guide explains how enterprise ITAM can improve asset visibility, reduce license waste, manage the IT asset lifecycle, and strengthen IT operations.

What is IT Asset Management?

IT Asset Management is the practice of managing an organization’s technology assets from acquisition through retirement. It combines inventory, financial, contractual, operational, and usage information to create a current view of the technology environment. ITAM typically covers hardware, software, cloud resources, SaaS applications, licenses, and related infrastructure.

For enterprise IT teams, the value comes from connecting this information. Instead of maintaining separate spreadsheets for devices, software licenses, procurement records, contracts, and users, ITAM can bring relevant data together and make it available for IT operations, finance, procurement, security, and business leaders.

Why does ITAM matter?

ITAM can help organizations:

  • Maintain complete hardware and software visibility: A comprehensive hardware and software asset tracking enterprise approach captures asset type, make, model, serial number, assigned user, department, location, purchase cost, warranty status, installed software, license information, and lifecycle status.
  • Keep asset information current: Automated discovery can continuously identify devices, software, and changes across the environment, while integrations with ITSM, endpoint management, procurement, and financial systems provide additional context.
  • Improve Shadow IT visibility across the enterprise: Discover unauthorized SaaS applications, cloud resources, and unmanaged devices that employees or departments may adopt outside established IT processes, giving teams greater visibility into potential security, compliance, and spending risks.
  • Understand how applications are being used: Identify application owners, active users, usage patterns, data access, costs, and business requirements to determine whether technology should be approved, consolidated, reassigned, or retired.
  • Reduce software license waste: A software license audit-managed approach can compare purchased entitlements with actual deployments and usage, helping identify inactive accounts, unused licenses, duplicate subscriptions, and over- or under-licensed applications.
  • Improve software renewal and procurement decisions: License usage, contract terms, renewal dates, and historical spending give procurement and IT teams better information for negotiating renewals, consolidating tools, and planning future purchases.
  • Strengthen security and compliance: Accurate asset records help identify vulnerable, unmanaged, outdated, or unsupported technology and give security teams a clearer understanding of the enterprise technology environment.
  • Support IT asset lifecycle management: Track assets from request and procurement through deployment, maintenance, renewal, reassignment, replacement, and secure retirement to improve utilization and control costs.
  • Turn asset data into better IT decisions: Connecting asset, financial, usage, procurement, and contract information gives IT and business leaders a reliable foundation for budgeting, technology planning, and investment decisions.

ITAM vs ITSM Difference

Understanding ITAM vs ITSM differences is important because the two disciplines serve different purposes while working closely together.

  • ITAM focuses on the technology assets an organization owns or uses, including their cost, ownership, lifecycle, usage, licensing, and status.
  • IT Service Management (ITSM) focuses on delivering and supporting IT services through processes such as incident management, service requests, change management, and problem management.

The two work together. For example, when an employee raises a support ticket for a laptop, ITSM manages the service request while ITAM can provide information about the device, assigned user, configuration, warranty, and software installed on it. ITAM data can also support a CMDB by providing information about assets and their relationships with business services.

Modernizing ITSM Software: Reinventing Service Delivery Through AI and Automation

Download the White Paper

Understanding IT Asset Lifecycle Management

IT asset lifecycle management covers every stage of an asset’s journey through the organization.
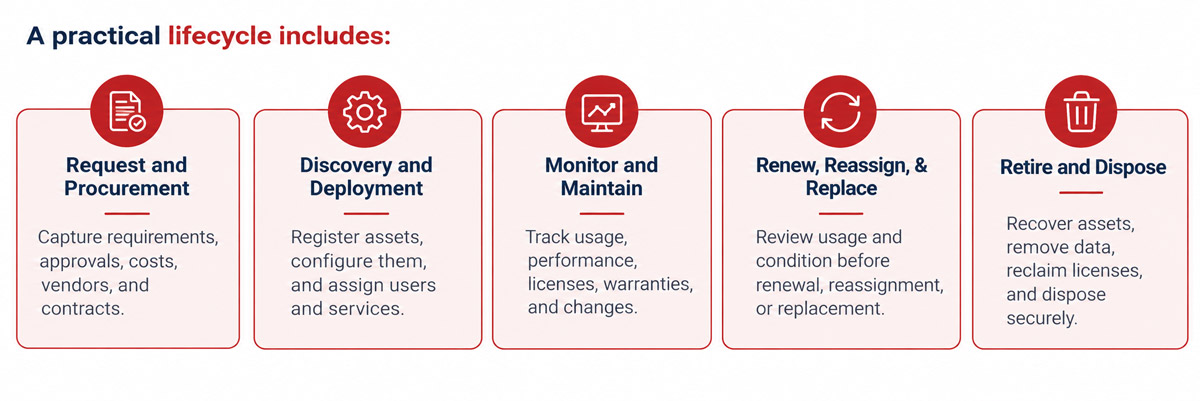
IT asset lifecycle management infographic showing five stages: request and procurement, deployment, maintenance, renewal, and disposal

Managed ITAM Services: Automating Asset Management

As enterprise technology environments expand across offices, remote users, cloud platforms, SaaS applications, and connected devices, manually maintaining asset records becomes increasingly difficult. Managed ITAM services provide continuous discovery, monitoring, reconciliation, reporting, and lifecycle management, helping organizations maintain accurate asset data without placing the entire operational burden on internal IT teams.

Managed ITAM services can help IT teams:

  • Discover New Devices and Software Automatically: Continuously identify hardware, software, applications, and other technology assets across the enterprise.
  • Keep Asset Records Accurate and Up to Date: Automatically update asset information as devices, users, configurations, and software change.
  • Detect Configuration and Ownership Changes: Identify changes to device configurations, assigned users, locations, or installed software for better asset control.
  • Identify Unused and Unauthorized Software: Flag applications that are inactive, unapproved, duplicated, or operating outside established IT processes.
  • Monitor Software License Utilization: Compare license allocations with actual usage to identify opportunities for reclamation, reassignment, or consolidation.
  • Automate Renewal and Warranty Alerts: Notify IT and procurement teams about upcoming software renewals, contracts, warranties, and support expirations.
  • Track Assets Approaching End of Life: Identify aging hardware and software so teams can plan replacements, upgrades, and retirement activities.
  • Reconcile Inventory Across IT Systems: Compare asset information across ITAM, ITSM, endpoint management, procurement, and financial systems to identify data gaps.
  • Generate Asset and Compliance Reports: Provide current reporting on asset inventory, licenses, lifecycle status, usage, costs, and compliance requirements.

IT Asset Management MSP Support for Growing Enterprises

As IT environments become more distributed and complex, organizations need continuous visibility into their hardware, software, SaaS applications, licenses, cloud resources, and associated costs. IT asset management services help bring this information together, while managed ITAM services provide the ongoing discovery, monitoring, license optimization, and IT asset lifecycle management needed to keep asset data accurate and actionable.

Synoptek helps organizations build and manage ITAM environments with the right combination of discovery, automation, governance, reporting, and integration across ITSM, procurement, security, and financial systems. As an experienced IT asset management MSP, Synoptek can help enterprises strengthen shadow IT visibility in enterprise environments, optimize software licenses, improve hardware and software asset tracking, and manage technology from procurement through retirement.
Explore IT Asset Management Services to Improve Visibility, Control Costs, and Strengthen IT Operations

Talk to Our Experts

Why Implemented Systems Still Fail at Exit - Technology Due Diligence

Thought LeadershipBudget Backwards From Exit: Implemented is not the Same as Operational

Read More

An implemented system that lacks operational readiness at exit becomes a diligence finding rather than an asset. Stop treating implementation and operationalization as sequential phases. Build operational readiness in parallel and plan every technology investment backward from the exit date.

Picture a project plan where every line is green: the platform is live, the vendor has signed off, and the steering committee has moved on to the next initiative. However, when someone asks who owns data quality in the new system, who gets the call when it breaks, and whether the reports leadership relies on can be trusted, nobody has a clear answer.

“Live” is a milestone on a project plan. “Operational” means the business can run the system reliably. They are not the same thing, and the gap between them is where portfolio companies quietly lose value.

I received a question on exactly this topic at the close of Synoptek’s recent session, hosted by ACG. It asked how to balance implementation timing against operationalization. My answer was that balance is the wrong frame, because it treats the two as phases competing for the same calendar.

Implementation and Operationalization are not Sequential Phases

If you wait until the system is built to think about how the business will run it, you have already waited too long.

Treating the two as consecutive phases creates a handoff at the worst possible moment. The project team is leaving, the business is least prepared to take over, and the first real test of the system happens in production, with customers and employees watching.

The alternative is to run them in parallel from the start.

What Operational Readiness Looks Like During the Build

Five things need answers while the system is still being implemented:

Process ownership.
Who supports it, and who owns it once the project team leaves?
Training.
Who needs training, and what does the plan cover?
Controls and data quality.
What data standards apply, and who monitors them?
Reporting.
Which reports will leadership rely on, and how will the team validate them?
Escalation.
What happens when something breaks, and who handles the escalation?

Then bring the people who will use the system into the final-state design decisions and the pre-go-live checklist. They find practical issues that the implementation team usually does not see. Better to hear about them before launch than after.

Safe to Go Live is Not the Same as Fully Mature

Parallel does not mean perfect on day one. You do not need every operational capability fully mature at go-live.

What you need is a clear line between two lists. The first is what must be ready for a safe go-live. The second is what can mature over the next 30, 60, and 90 days, with a plan to address over time.

I think of this as progressive operationalization. Define the operating model early. Embed readiness into role milestones. Then mature it deliberately over time. Go-live should not be the point where business adoption begins. Adoption should already be underway.

The Second Clock Running Inside Every Portfolio Company

My colleague Eric Codorniz added a point that reframes the question for sponsors and operating partners.

In a portfolio company, there is a second clock running. The exit date sets that clock, not the project plan. Here is why. A buyer’s team tests whether contracts and licenses transfer, reviews incident history, and checks how much of the business depends on one person or one vendor. Anything asserted without evidence gets discounted: a run rate described as normalized, integration work described as handled, and other unproven claims.

An operational system produces evidence: an owner, a support history, documented controls, and reports that reconcile. An implemented system produces a claim.

Eric’s conclusion was simple. Budget backwards from exit, not forward from kickoff. Work started a year out gets credited to earnings. The identical work started three months out shows up as a finding.

Where the Integration Money Actually Goes

One slide in the session drew on an EY study of 229 deals. Companies that exceeded their synergy targets invested about 8 percent more in integration than those that fell short.

Eric’s read of that number is that the extra spend is not implementation. It is operationalization: the training, the ownership, the controls, and the adoption work that turns a live system into a working one. That is his interpretation, not a finding of the study, which reports the spending gap and not what the money bought. But it points to where the discipline pays.

A Practical Test for Every System in Flight

For any system currently being implemented in your portfolio, three questions will reveal whether the system is operationally ready:

1
Who owns this system, its data, and its support after the project team leaves?
If the answer is “the vendor” or “we will figure it out,” operationalization has not started.
2
What must be true at go-live to be safe, and what is the 30-, 60-, and 90-day plan for everything else?
If there is only one list, the plan ends at launch.
3
Working backward from the planned exit date, will this be an operating asset or an open question for the buyer’s team?
If you cannot say, the second clock is already running against you.

The Question That Changes the Conversation

The question most steering committees ask is whether a system is live. The more useful question is whether it works without us.

Systems that pass that test are assets a buyer can verify. Systems that do not are findings a buyer will price. The difference is decided long before the sale process starts, by whether anyone budgeted for the work that comes after go-live.

Watch the full session on demand, including the live Q&A discussed here: Managing IT Value, Risk, and Spend Across the Deal Lifecycle.


Unified commerce technology linking e-commerce platform and ERP for omnichannel retail

BlogE-commerce ERP Integration: Building a Connected Digital Commerce Ecosystem

Read More

Key Takeaways

  • Modern commerce depends on the integration between the customer-facing storefront and the enterprise systems operating behind it.
  • Disconnected e-commerce, ERP, inventory, CRM, and fulfillment systems can create data inconsistencies, manual processes, and customer experience gaps.
  • E-commerce integration with ERP provides a foundation for accurate product, pricing, inventory, customer, and order information.
  • An omnichannel retail strategy requires connected inventory, order, and fulfillment systems across digital and physical channels.
  • AI and commerce analytics can improve product discovery, personalization, merchandising, customer service, and decision-making.
  • Ongoing managed commerce support helps businesses monitor, maintain, optimize, and evolve their commerce ecosystem after launch.

The Technology Challenges Behind Modern Commerce

For a customer, buying something online can appear remarkably straightforward: search for a product, review the available options, add an item to the cart, complete checkout, and receive an order confirmation. However, behind that seemingly simple journey, multiple technology systems may need to exchange information in real time, including the B2B e-commerce platform, ERP, payment gateway, inventory system, CRM, order management system, warehouse management system, fulfillment platforms, and AI chatbots.

That complexity creates a fundamental challenge for retailers, manufacturers, and distributors: how do you make a fragmented technology environment feel like one seamless commerce experience? Here’s what makes modern commerce a challenge for many today:

  • Disconnected e-commerce and ERP systems: E-commerce integration with ERP is critical. When ERP and storefront systems operate in silos, product, pricing, inventory, customer, and order information may require manual intervention or periodic synchronization, increasing the risk of inconsistencies and delays.
  • Inaccurate or fragmented data: Customers expect to see whether a product is available and when they can receive it. When inventory information is spread across stores, warehouses, distribution centers, and digital channels, maintaining accurate availability can become difficult.
  • Complex omnichannel experiences: Effective omnichannel fulfillment requires businesses to coordinate product information, pricing, inventory, orders, and fulfillment across websites, mobile commerce, marketplaces, and physical stores while maintaining a consistent customer experience.
  • Manual order and fulfillment processes: Orders often pass through an order management system and several other systems after checkout. If those systems do not communicate effectively, teams may need to re-enter information, manually track orders, or resolve fulfillment issues, adding unnecessary operational effort.
  • Legacy integrations and growing technology complexity: Commerce ecosystems often combine modern platforms with older enterprise applications and custom integrations. Maintaining these connections as platforms, APIs, and business requirements change can become increasingly challenging.
  • Limited visibility across the commerce lifecycle: Businesses need visibility from product discovery and checkout through inventory, fulfillment, delivery, returns, and customer service. Data trapped within individual systems can make it difficult to understand what is happening across the complete journey.
  • Increasing pressure to adopt AI: AI in e-commerce is increasingly being used for search, recommendations, personalization, merchandising, customer service, and commerce operations. However, AI initiatives depend on reliable data, connected systems, and an architecture capable of providing the right context.
  • Ongoing performance and support requirements: A B2B e-commerce platform can operate as a 24/7 revenue channel. Performance issues, failed integrations, payment problems, synchronization errors, and security vulnerabilities require ongoing monitoring and support rather than attention only during implementation.

What a Connected Digital Commerce Ecosystem Looks Like

A modern e-commerce experience depends on much more than the storefront. Customers expect easy product discovery, fast checkout, accurate pricing and availability, personalized recommendations, and flexible delivery and returns. Meeting these expectations requires B2B e-commerce platforms to work seamlessly with the enterprise systems and data that power commerce operations.

For organizations serving business buyers, a B2B e-commerce platform must also connect seamlessly with ERP, CRM, inventory, pricing, and order management systems. B2B e-commerce ERP integration can help synchronize these processes while supporting customer-specific pricing, catalogs, purchasing rules, and account structures.

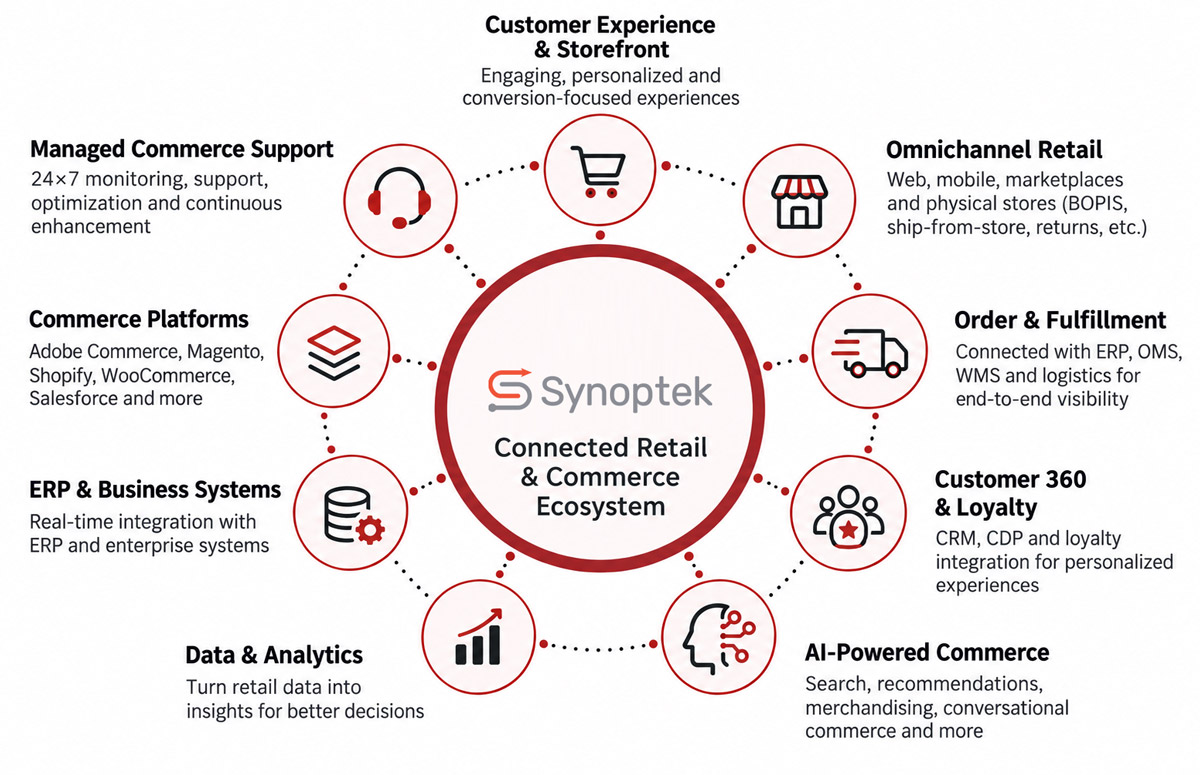
Here’s what defines a connected digital commerce ecosystem:

Connected commerce ecosystem showing e-commerce ERP integration with storefront, omnichannel retail, fulfillment, CRM, AI and analytics

  • Seamless Customer Experiences: Platforms such as Adobe Commerce, Magento, Shopify, WooCommerce, and Salesforce Commerce Cloud provide the foundation for digital storefronts, but customer experience depends on how effectively these platforms connect with ERP, CRM, inventory, payment, marketplace, and fulfillment systems. The goal is to make this underlying complexity invisible to customers while delivering consistent, convenient, and relevant B2C and B2B buying experiences.
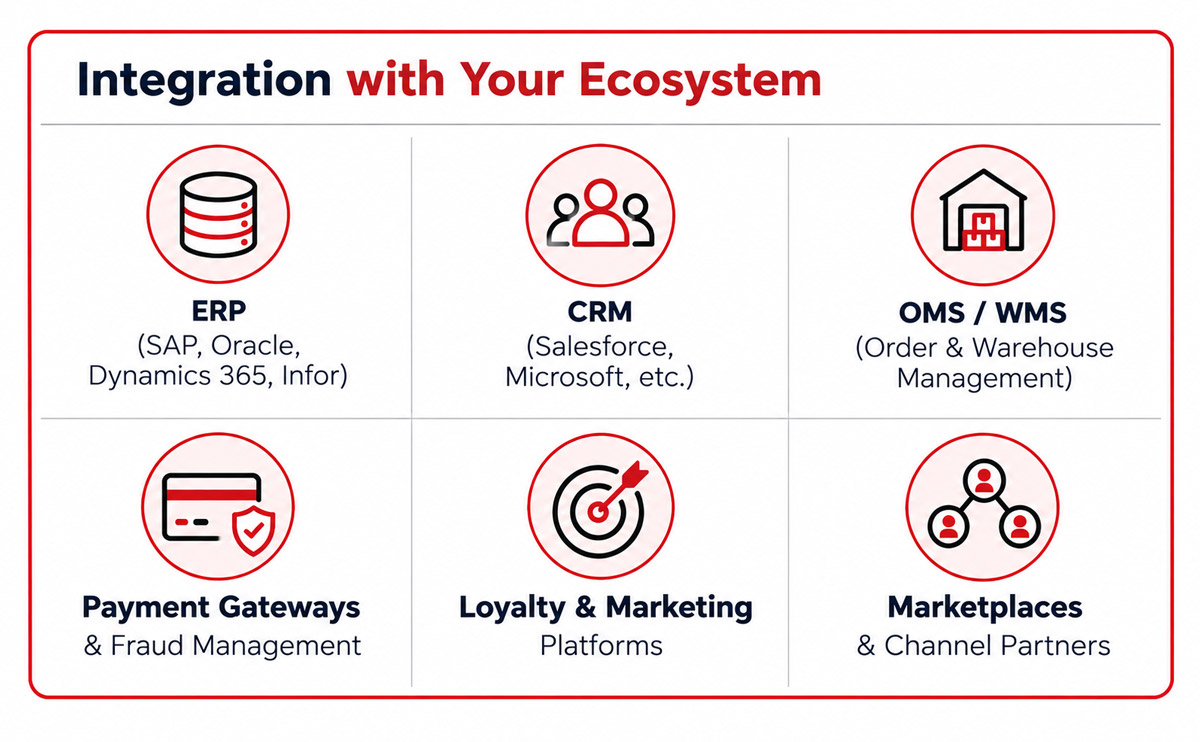
  • E-commerce ERP Integration: E-commerce ERP integration connects the storefront with critical business data, including products, catalogs, pricing, promotions, customer accounts, inventory, orders, fulfillment status, and complex product structures such as bills of material. Automated data flows can reduce manual entry, minimize discrepancies, and ensure customers and employees have access to more consistent information. Choosing the right ERP for e-commerce helps businesses create reliable connections between their commerce platforms and core business operations while supporting scalable data and order flows.

E-commerce integration with ERP systems like SAP, Oracle, Dynamics 365 and Infor, plus CRM, OMS/WMS, payment gateways and marketplaces

  • Connected Omnichannel Fulfillment: Customers increasingly move between websites, mobile devices, marketplaces, and physical stores as part of the same buying journey. According to PWC, 89% of customers are retained by businesses that have a strong omnichannel retail strategy. Enabling unified commerce can deliver real-time inventory visibility, Buy Online, Pick Up In Store (BOPIS), Click and Collect, ship-from-store, Buy Online, Return In Store, and consistent product, pricing, and promotion experiences across channels.
  • Unified Customer Data: Connecting e-commerce transactions with CRM, customer data, and loyalty platforms can create a more complete view of customer interactions and purchase history. This digital commerce platform integration can support Customer 360 initiatives, personalized promotions, loyalty programs, relevant recommendations, and more targeted B2B and B2C engagement across channels.
  • Intelligent AI in E-Commerce: AI in digital commerce can enhance product search, recommendations, personalization, conversational commerce, merchandising, product content, customer service, and cross-sell opportunities. Its potential extends beyond the storefront: when AI can access relevant product, customer, inventory, behavioral, and transaction data, it can support more intelligent commerce experiences and operations.
  • Actionable Commerce Analytics: Connecting e-commerce, ERP, inventory, customer, order, and fulfillment data creates a stronger foundation for commerce analytics. With 67% of online shoppers abandoning their carts because delivery is too expensive, slow, or unclear, commerce analytics can help businesses identify where customers drop off and why. They can analyze cart abandonment, conversion rates, product and category performance, buying behavior, inventory movement, fulfillment performance, and channel trends, turning fragmented data into actionable insights for better customer experiences and more informed decisions.
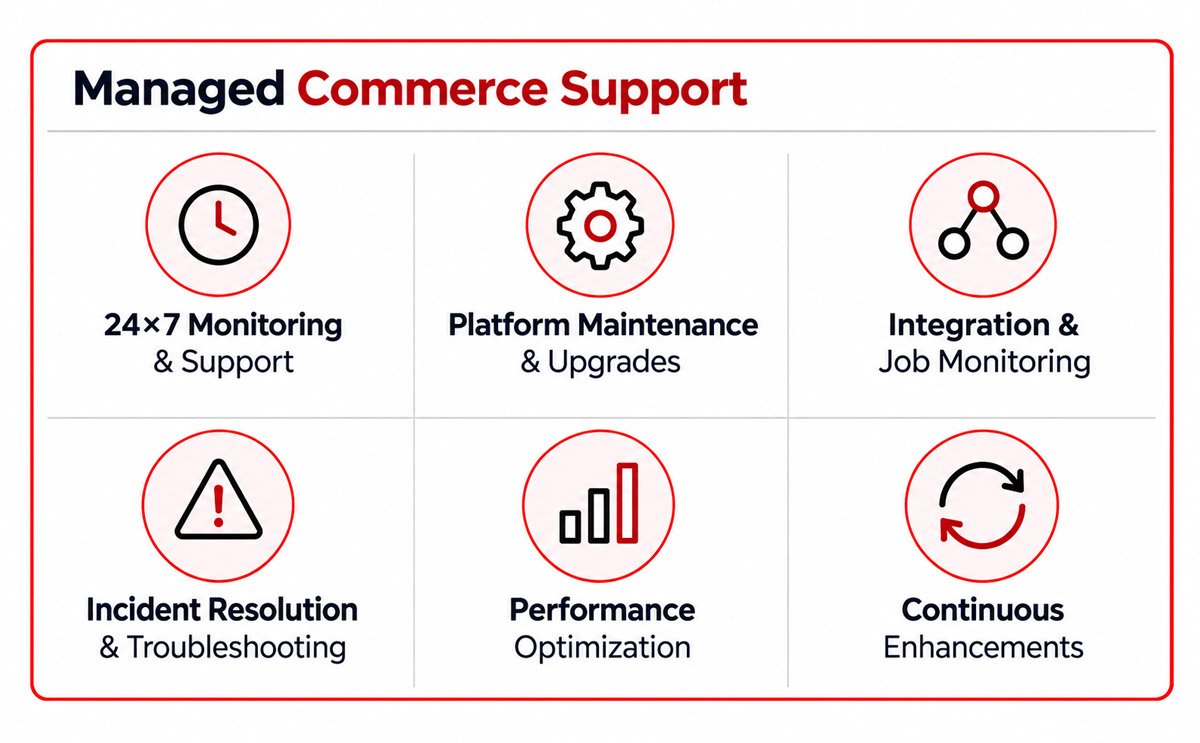
  • Managed Commerce Support: Digital commerce requires ongoing monitoring and optimization after go-live to keep platforms, integrations, data flows, and customer-facing experiences running reliably. Managed commerce support can help businesses monitor platform performance, APIs, ERP integrations, inventory and order synchronization, checkout and payments, while providing troubleshooting, incident resolution, upgrades, security updates, performance optimization, and continuous improvements as commerce needs evolve.

Managed commerce support with 24x7 monitoring, platform upgrades, integration and job monitoring, incident resolution and performance optimization

How Synoptek Streamlines E-commerce ERP Integration

Synoptek works with retailers, manufacturers, and distributors to build, integrate, modernize, manage, and continuously optimize digital commerce ecosystems across B2C and B2B environments. Our approach brings together unified commerce technology, enterprise systems, data, integrations, automation, and AI to create a more connected and scalable commerce environment.

We connect the storefront with the enterprise systems, data, processes, and technologies that support every stage of the customer and commerce journey. Our capabilities span commerce platforms, e-commerce ERP integration, omnichannel retail strategy, CRM, order and fulfillment integration, data and analytics, automation, AI, and managed commerce support. Depending on business requirements, this can include modernizing an existing commerce environment, integrating new capabilities, improving omnichannel fulfillment, or developing and optimizing digital commerce operations across technologies such as Adobe Commerce, Magento, Shopify, WooCommerce, and Salesforce Commerce Cloud.

Through Managed Commerce Support, Synoptek can monitor platforms, integrations, APIs, scheduled jobs, data synchronization, checkout, and payments while supporting troubleshooting, upgrades, security updates, performance optimization, scalability, incident resolution, and ongoing feature development.

Synoptek Digital Commerce Capabilities

Commerce Platforms

Adobe Commerce | Magento | Shopify | WooCommerce | Salesforce Commerce Cloud

Connected Enterprise

E-commerce + ERP | B2B E-Commerce | CRM | OMS/WMS | Inventory | Order & Fulfillment

Digital Intelligence

Data & Analytics | Automation | AI in E-Commerce | Personalization | Business Insights

Continuous Operations

Platform Monitoring | Integration Support | Performance Optimization | Security | Upgrades | Managed Commerce

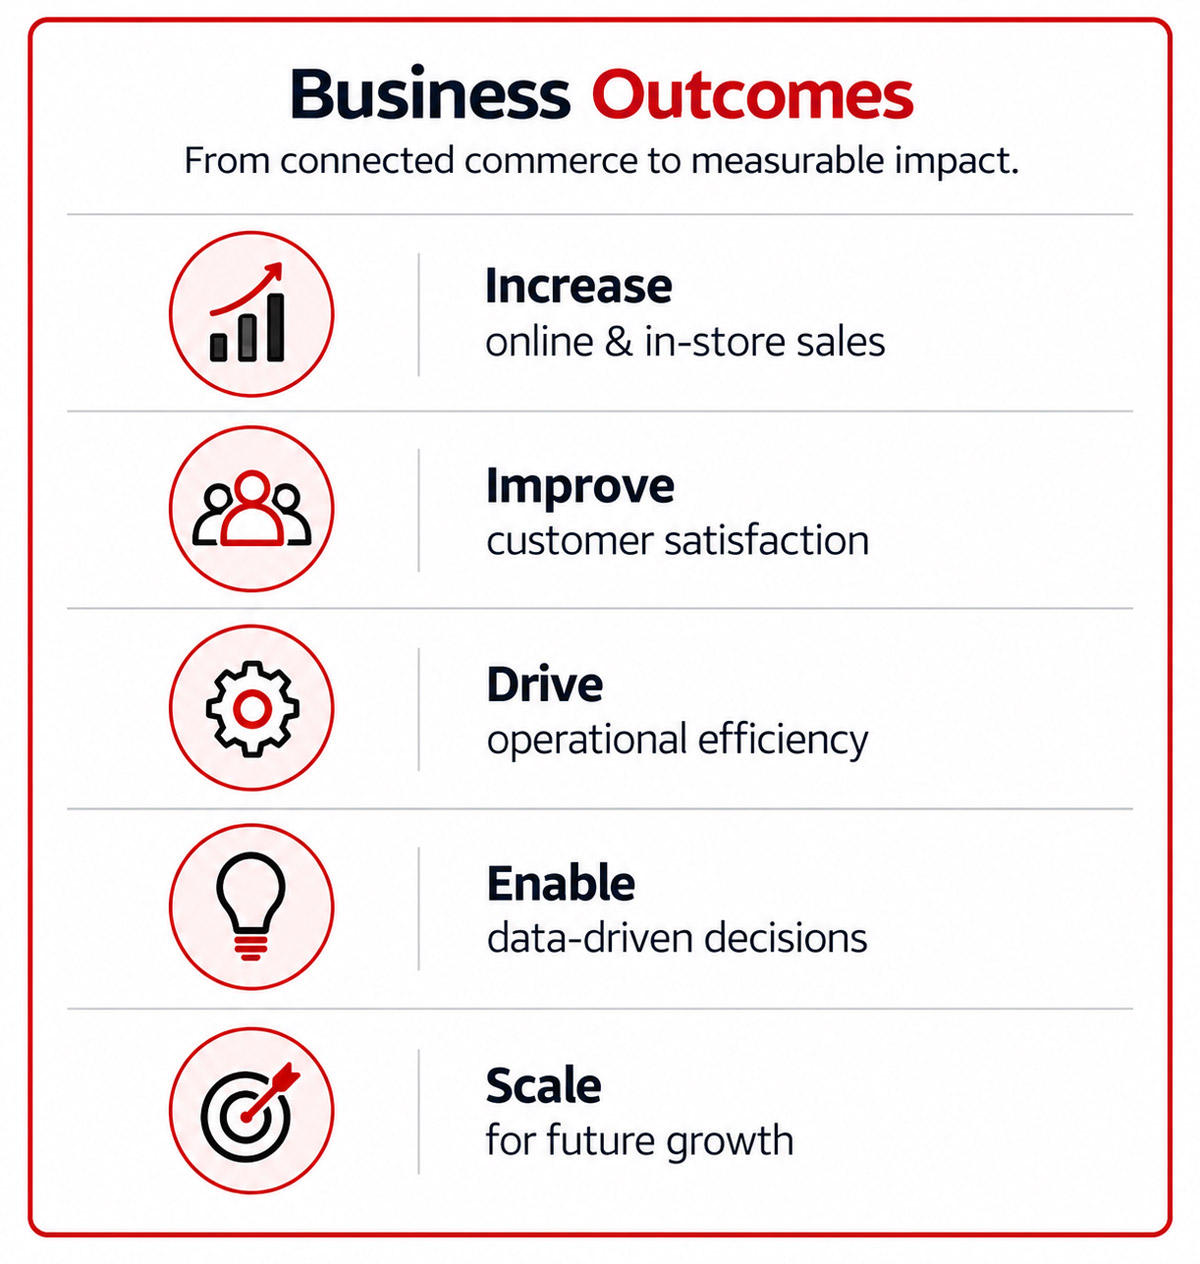
Business outcomes of unified commerce: higher online and in-store sales, customer satisfaction, operational efficiency and data-driven decisions

Building a Connected, Intelligent, and Scalable Commerce Ecosystem

Modern commerce brings together far more technology than customers see. The storefront provides the visible experience, but ERP, CRM, inventory, order management, fulfillment, analytics, integrations, automation, and AI all influence what happens behind every transaction.

When these systems remain disconnected, businesses can encounter inconsistent data, manual processes, limited visibility, operational delays, and fragmented customer journeys. When they work together, organizations can create more consistent experiences while gaining greater visibility into the operations that support them.

For retailers, manufacturers, and distributors, the next phase of digital commerce is about connecting the technologies behind every channel and creating an ecosystem that can evolve with the business. Commerce platforms, ERP, CRM, OMS/WMS, data and analytics, integration, automation, AI, and managed support each play a role in building that foundation.

The storefront is what customers see. The connected technology ecosystem behind it is what makes modern commerce work. Together, these capabilities create a digital commerce ecosystem where customer experiences, enterprise operations, data, and technology work together rather than operating as disconnected systems.

AI-ready ERP trusted data foundation

Thought LeadershipConnected, Governed, Trusted: The Data Foundation for AI-Ready ERP

Read More

AI-ready ERP starts with trusted data. Strong data governance, quality controls, and shared business definitions help AI deliver reliable insights and decisions. Connecting ERP with other business systems provides the context AI needs, while modern integration architectures ensure secure, timely access to information. With the right data foundation, organizations can improve AI adoption, operational efficiency, and business outcomes.

Every major ERP platform now ships with AI built in: Copilot in Microsoft Dynamics 365, Joule in SAP, and embedded AI agents in Oracle Fusion Cloud ERP. They promise sharper forecasts, smarter recommendations, and processes that run themselves. But none of them can compensate for poor underlying data.

AI Moves Fast, So Do Its Mistakes

AI can process information and act on it at a speed and scale no team can match. That is a gift when your master data is sound. It amplifies the quality of the underlying enterprise data, making data accuracy and consistency critical to reliable outcomes. But AI moves fast, and so do its mistakes. When records are inaccurate, duplicated, incomplete, or outdated, the same speed spreads errors across decisions and processes before anyone notices.

The Trust Deficit

Fragmented supplier records, stale inventory balances, inconsistent customer information, and conflicting product hierarchies produce recommendations that look credible but are operationally wrong. This results in:

  • Incorrect demand and inventory forecasts
  • Duplicate or inappropriate supplier recommendations
  • Misleading customer profitability analysis
  • Inaccurate cash-flow and working-capital predictions
  • Automated actions based on outdated business information

The damage does not stop at bad decisions. When employees repeatedly question what the AI tells them, they quietly return to manual analysis. Adoption falls, productivity gains stall, and the return on your AI investment shrinks.

Trust in enterprise AI begins with trust in enterprise data.

Building the Foundation of Trust

Three data disciplines make ERP information accurate, understandable, traceable, and usable by AI.

1. Master Data Management and Data Quality

Start with governed, authoritative records for customers, suppliers, products, employees, assets, and financial dimensions. That means:

  • Entity matching and deduplication
  • Data-quality validation and monitoring
  • Standardized identifiers and classifications
  • Defined ownership and stewardship
  • Continuous synchronization across systems

One clarification worth making: AI applications typically use this governed information for grounding and decision support, not necessarily for training the underlying model. The point is that the answers it gives are anchored in records you trust.

2. Metadata and Data Lineage

Metadata explains what the data represents. Lineage shows where it came from, how it was transformed, and when it was last updated. Together, they let both AI and people judge whether a piece of data is relevant, fresh, and reliable.

3. Semantic Models and Business Vocabulary

Semantic models translate technical data structures into consistent business concepts, so AI understands that different system terms may describe the same customer, product, revenue measure, or business event. The payoff:

  • Consistent KPI interpretation
  • Natural-language interaction with enterprise data
  • More accurate cross-system analysis
  • Traceable, explainable AI responses

Accurate data tells AI what happened. Metadata and semantics help it understand what the data means.

Beyond ERP: The Context AI Needs

An intelligent ERP cannot operate in isolation. ERP provides the essential transactional record, but many decisions depend on information from outside the core platform: CRM pipelines and customer interactions, warehouse and supply-chain telemetry, commerce and point-of-sale activity, supplier and logistics platforms, contracts, emails and service records, and economic, weather, market and geopolitical signals.

Connecting financial, customer, product, supply-chain, workforce and external data gives AI a 360-degree view of the business, rather than one isolated transaction.

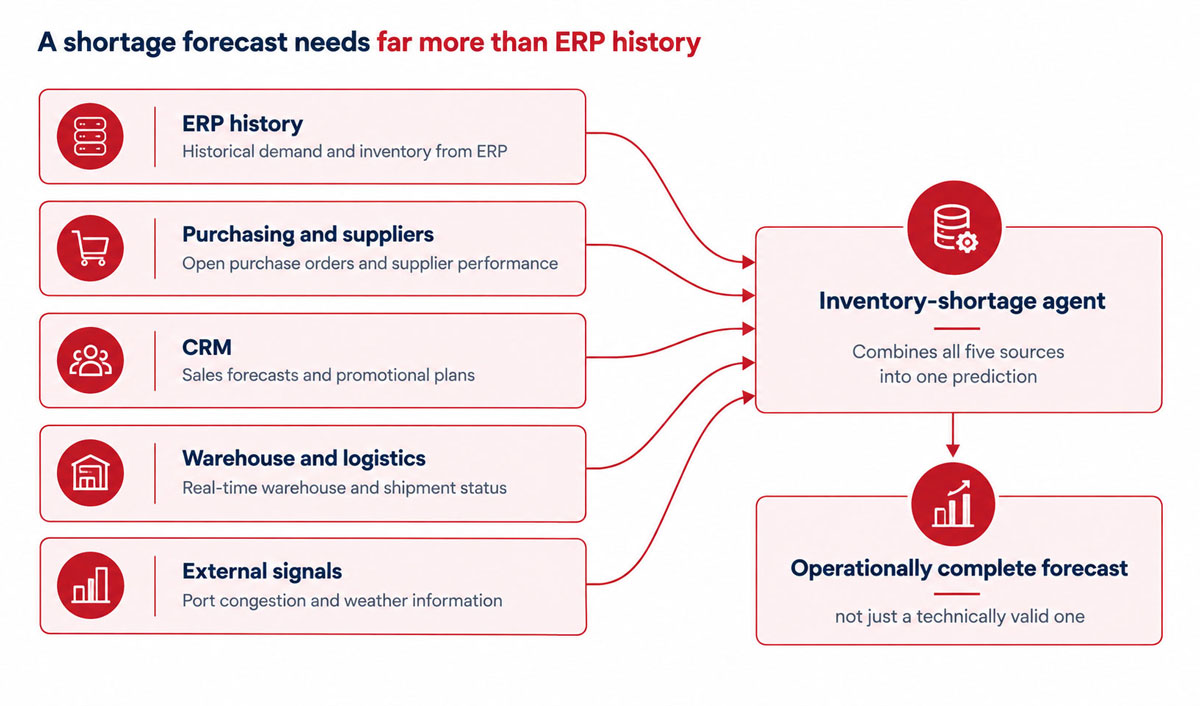
Take inventory risk. An AI agent predicting a shortage may need to combine five kinds of information:

AI inventory-shortage agent combining ERP history, purchasing, CRM, warehouse and external data into a complete forecast

Without the full picture, the agent can produce a forecast that is technically valid but operationally incomplete.

ERP supplies the transactional core; connected data supplies the decision context.

An Architecture that Delivers Data at the Point of Decision

The goal is to connect ERP and surrounding data without adding complexity, latency, or uncontrolled duplication. That means moving from brittle legacy pipelines toward event-driven data fabrics, where systems are decoupled, and AI applications and business users can securely reach high-quality data in real time.

  • Beyond batch and point-to-point. Traditional ETL and point-to-point interfaces still suit some workloads. Relying on them exclusively, though, creates latency, brittle dependencies, duplicated data, and heavy maintenance, especially for real-time AI use cases.
  • Lakehouse and data fabric. A lakehouse brings structured ERP data together with contracts, documents, emails, sensor data, and logs. A data-fabric approach adds consistent discovery, access, integration, security, lineage, and governance across distributed and hybrid environments.
  • Event-driven, real-time data. Event-driven integration lets AI react to an order cancellation, inventory movement, equipment alert, or delayed shipment without waiting for the next batch cycle.
  • Zero-copy and reduced-copy patterns. These let systems securely access data without repeatedly moving and storing it, which means:
    • More current information for AI
    • Reduced replication and storage
    • Fewer synchronization failures
    • Improved governance over distributed copies
    • Faster access to cross-platform data

Choose these patterns based on performance, security, sovereignty, resilience, and workload needs. They are not a universal replacement for data movement.

The objective is not simply to centralize data. It is to make trusted data securely accessible when and where intelligence is needed.

How Ready Are You? A Practical Assessment

Use these seven factors to evaluate whether your organization can support trusted AI within ERP and operational processes.

Readiness Factor Traditional State AI-Ready Target Immediate Action
Data quality and MDM Siloed, duplicated records; manual correction Governed golden records with continuous quality monitoring Measure duplicate, incomplete, and inaccurate records across critical entities
Business context ERP data analyzed apart from customer, supply-chain, and external data Connected operational data organized around business domains and decisions Identify the additional data needed for three priority AI use cases
Metadata and semantics Technical field names; inconsistent KPI definitions Shared business vocabulary, semantic models, and standardized metrics Reconcile terminology and KPI definitions across ERP, CRM, and analytics
Integration architecture Point-to-point interfaces, batch ETL, and redundant copies API-led, event-driven, lakehouse-enabled, reduced-copy architecture Assess latency, replication costs, and failure points in current integrations
Governance and lineage Periodic cleansing; limited accountability or traceability Continuous governance, named ownership, lineage, and policy-based access Assign data owners and stewards for critical business domains
AI grounding and controls Broad or inconsistent access to unverified information AI grounded in approved, current, access-controlled data Define approved data sources, access boundaries, and freshness requirements
Measurement and adoption Pilots measured by technical completion Adoption, trust, accuracy, business value, and risk measured continuously Establish baselines for accuracy, user trust, process time, and business outcomes

Where Do You Stand? Five Readiness Levels

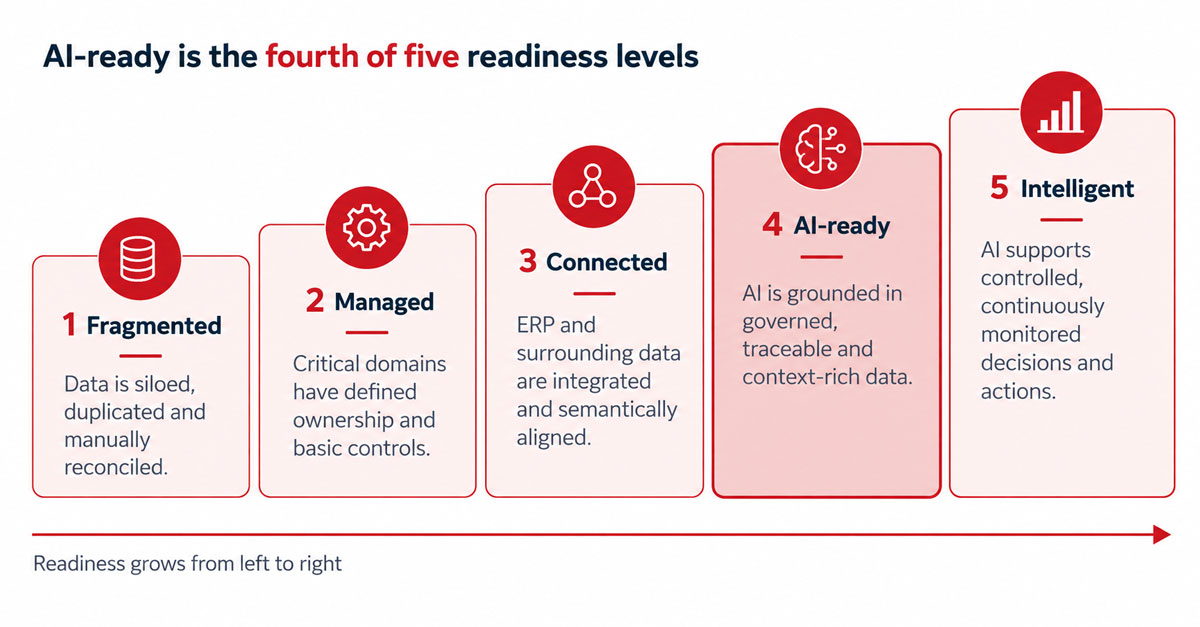
Beyond the factor-by-factor view, you can place your organization on one of five measurement levels:

Five ERP data readiness levels: Fragmented, Managed, Connected, AI-ready and Intelligent, with AI-ready as level four

At level four, AI is grounded in governed, traceable, context-rich data. Level five adds controlled, continuously monitored operational decisions and actions.

The Takeaway

AI-ready ERP is not achieved by adding an AI layer to existing systems. It takes four things working together:

  • A trusted data core: governed master data and continuous quality
  • Shared business meaning: metadata, lineage and semantic models
  • Connected operational context: ERP plus the data around it
  • An architecture that delivers governed information at the point of decision

A good first step is small: measure the duplicate and incomplete records in your most critical entities, name their owners, and pick three AI use cases to connect first. Trusted data comes before intelligent operations.


Dynamics 365 Finance and Operations Case Study | Synoptek

Case StudyDynamics 365 Finance and Operations Unifies Global Operations for a Consumer Goods Company

Read More
Microsoft Fabric vs. Data Lake: Choosing the Right AI Foundation

BlogFabric vs. Data Lake: A Microsoft Fabric Consulting Guide

Read More

Key Takeaways

  • A data lake primarily provides scalable storage for large volumes of structured, semi-structured, and unstructured data.
  • Microsoft Fabric brings data integration, engineering, storage, analytics, real-time intelligence, Power BI, and AI capabilities into a unified platform.
  • OneLake serves as the shared data foundation across Microsoft Fabric workloads, reducing the need to duplicate data between analytics experiences.
  • Choosing the right AI data architecture requires evaluating data quality, governance, accessibility, integration, skills, analytics requirements, and long-term business goals.
  • A Microsoft Fabric partner can help organizations assess their existing data environment, compare architectural options, and determine where Fabric can support their AI and analytics strategy.
  • Microsoft Fabric consulting can help organizations develop a practical roadmap for integrating, modernizing, or transitioning their data environment without adding unnecessary complexity.

As organizations move from experimenting with AI to deploying it across the business, one question becomes increasingly important: where should the data powering those AI initiatives live, and how should teams manage it?

For some organizations, a data lake provides the flexibility and scale they need. For others, a broader platform such as Microsoft Fabric helps simplify the journey from data ingestion to analytics and AI.

The answer is not always one or the other. Understanding the difference between Microsoft Fabric vs. data lake can help organizations determine which architecture better fits their data and AI requirements. This guide explores the differences and provides tips on choosing the right option.

What is a Data Lake?

A data lake is a centralized repository to store large volumes of data in its original or relatively raw form. It can accommodate structured, semi-structured, and unstructured information, making it useful for organizations working with everything from transactional records and application logs to documents, images, and machine-generated data.

The flexibility of a data lake makes it particularly useful for data engineering, data science, advanced analytics, and AI experimentation. Teams can ingest and retain data before determining how it should be transformed and analyzed for different use cases.

However, flexibility can also create challenges. Without clear governance, metadata, ownership, security, and data-quality processes, a data lake can become difficult to navigate and trust. As data volumes grow, organizations may also need additional tools and processes for integration, cataloging, governance, analytics, and visualization.

What is Microsoft Fabric?

Microsoft Fabric is a unified analytics platform that brings together capabilities for data integration, data engineering, data science, data warehousing, real-time intelligence, analytics, and business intelligence.

At the foundation of Fabric is OneLake, Microsoft’s tenant-wide data lake. Fabric workloads use OneLake as a shared data foundation, allowing data to be reused across different experiences without requiring unnecessary duplication.

Fabric also includes lakehouses, warehouses, Data Factory capabilities, Power BI, Real-Time Intelligence, Fabric databases, and data science capabilities within the same broader platform. This can reduce the number of separate technologies teams need to connect and manage.

Food Service Distributor Gains Enterprise-wide Visibility with Microsoft Fabric

Read the Case Study

Microsoft Fabric vs. Data Lake: Key Differences

A traditional data lake can provide the foundation for AI experimentation and large-scale data processing. Microsoft Fabric combines multiple data and analytics capabilities, including lakehouse architecture through Fabric lakehouses, with business intelligence, real-time analytics, and AI capabilities.

Capability Data Lake Microsoft Fabric
Scalable data storage Strong Strong through OneLake
Structured & unstructured data Yes Yes
Data engineering Requires supporting tools Built into the platform
Data integration Requires integration tooling Integrated capabilities
Business intelligence Requires additional platforms Power BI integration
Data warehousing Separate technology typically required Fabric Warehouse
Real-time workloads Requires additional services Fabric Real-Time Intelligence
AI and data science Depends on selected tools and services Integrated data science and analytics capabilities
Governance Depends on architecture, tools, and processes Built-in governance capabilities with Microsoft ecosystem integration
Platform management Multiple components may be required Unified SaaS platform

Which is Better for AI: Microsoft Fabric or a Data Lake?

For organizations considering a data lakehouse approach, Microsoft Fabric can provide a managed environment that connects lakehouse architecture with analytics, BI, and AI capabilities. The better choice depends on the AI use case and the organization’s existing data environment.

  • A data lake can be a strong choice when an organization needs to collect and retain large volumes of diverse data for experimentation, machine learning, advanced analytics, or future use. Data scientists and engineering teams can work with raw data and develop their own processing and modeling approaches.
  • Microsoft Fabric is attractive when organizations want to connect those data capabilities with enterprise analytics and business users. Microsoft Fabric can also support AI and machine learning scenarios through its integration with Microsoft’s broader AI ecosystem.

When Should You Choose a Data Lake?

A data lake may be the right foundation when your organization needs flexibility, scalable storage, and support for diverse workloads. Consider a data lake when your organization:

  • Needs highly scalable storage for diverse datasets.
  • Works extensively with raw or unstructured data.
  • Has mature data engineering and data science teams.
  • Already has investments in cloud data platforms and analytics tools.
  • Needs flexibility to support multiple analytical or AI workloads.
  • Wants to build a specialized architecture around existing cloud services.

A data lake can provide a flexible foundation without requiring an organization to adopt a broader analytics platform immediately.

However, teams should account for the additional architecture required around the lake. Data ingestion, quality, governance, cataloging, security, orchestration, analytics, and visualization may require separate services and expertise.

When Should You Choose Microsoft Fabric?

Organizations that are already invested in Microsoft technologies may also benefit from working with a Microsoft Fabric partner to assess how Fabric fits into their existing data environment.

Consider Fabric when your organization:

  • Has significant Microsoft investments across Azure, Microsoft 365, and Power BI.
  • Wants to reduce fragmentation across data and analytics tools.
  • Needs a shared data foundation for engineering, analytics, BI, and AI.
  • Wants business users and technical teams to work from connected data.
  • Needs stronger governance and centralized data management.
  • Wants to accelerate the path from enterprise data to AI use cases.
  • Plans to expand its use of Power BI and Microsoft AI technologies.

Making the Right AI Data Decision with a Microsoft Fabric Partner

The choice between Microsoft Fabric and a data lake can have long-term implications for your data architecture, AI capabilities, costs, and operational complexity. A Microsoft Fabric partner can assess your current environment, help weigh the trade-offs between different approaches, and ensure the decision supports both immediate requirements and future AI initiatives.

A partner can:

  1. Assess your existing data environment: Understand where data currently resides, how much data the organization manages, which systems generate it, and how frequently it changes. The assessment should include cloud platforms, databases, applications, files, SaaS systems, and existing data lakes.
  2. Define your AI and analytics priorities: Identify whether the immediate need is machine learning experimentation, predictive analytics, enterprise reporting, generative AI, real-time intelligence, or a combination. Different workloads can require different data patterns and processing capabilities.
  3. Evaluate governance and security requirements: AI initiatives depend on trusted data. Review ownership, access controls, lineage, compliance, retention, and data quality requirements before selecting the architecture.
  4. Consider your technology ecosystem: Organizations already invested heavily in Microsoft technologies may benefit from Fabric’s integration across OneLake, Power BI, Data Factory, and other Fabric workloads.
  5. Calculate total complexity, not just storage cost: Compare the ongoing cost of infrastructure, integration, governance, administration, skills, and maintenance. A lower-cost storage platform can become more complex when teams need multiple additional technologies around it.

Building the Right Foundation for Your AI Strategy

Choosing Microsoft Fabric is only one part of building an AI-ready data foundation. Organizations also need to determine how Fabric fits within their existing data environment, which workloads should move, which platforms should remain, and where OneLake can provide value. Microsoft Fabric consulting can help assess the current data landscape, design the target architecture, establish governance, and develop a practical roadmap for analytics and AI.

The Microsoft Fabric vs. data lake decision is ultimately about more than choosing a storage technology. A data lake can provide the flexibility and scale needed for diverse data and AI workloads, while Microsoft Fabric brings data engineering, analytics, business intelligence, real-time workloads, and AI capabilities into a more integrated environment. For some organizations, Fabric may simplify the path from fragmented data to governed analytics and AI; for others, a data lake or hybrid approach may make more sense.

Need help determining whether Microsoft Fabric is right for your organization? Synoptek’s Microsoft Fabric consulting services can help you assess your existing data environment, evaluate your AI and analytics requirements, identify the right architecture, and build a practical modernization roadmap aligned with your business goals.

Talk to our Microsoft Fabric experts today.

SharePoint Migration Services: How to Plan a Successful SharePoint 2016 Migration

BlogSharePoint Migration Services: How to Plan a Successful SharePoint 2016 Migration

Read More

A successful SharePoint 2016 migration requires organizations to assess content, permissions, workflows, applications, integrations, dependencies, and business requirements before migration. SharePoint migration services can provide the expertise and execution support needed to move complex workloads to SharePoint Online, SharePoint Server Subscription Edition, or another appropriate destination while creating a cleaner, more manageable environment.

With SharePoint Server 2016 now out of support, many organizations are planning their migration or modernization efforts for 2026 and beyond. However, before planning the move, organizations should understand what end of support means for their existing environment and take a structured approach to manage complexity, reduce disruption, and protect critical business operations throughout the migration.

In this blog, we outline the key steps for planning a successful SharePoint Server 2016 migration, from preparing and piloting content to migrating in waves, minimizing disruption, and validating the results.

SharePoint Migration Services: Where Should You Start?

The starting point of a SharePoint migration can significantly influence the outcome of the entire project. Without a clear understanding of the existing environment, teams can overlook dependencies, underestimate complexity, or encounter issues after migration has already begun. A well-defined migration plan creates a shared understanding among IT teams, business owners, and users, helping keep the migration aligned with business requirements and reducing avoidable disruption.

Use this SharePoint migration checklist to cover the key planning activities before migration:

  • Define the Migration Scope: Establish which sites, libraries, lists, applications, and workloads the project will move. A clear scope prevents unexpected content from entering the migration plan.
  • Assign Business Ownership: Give each workload a business owner who can confirm requirements, validate migrated content, and approve the completed migration.
  • Map Dependencies: Document connections between SharePoint, applications, authentication, integrations, and other Microsoft services. These dependencies can affect migration sequencing and testing.
  • Set Acceptance Criteria: Define what each workload must pass before the team considers the migration complete. Include data accuracy, permissions, functionality, and user validation.

SharePoint Data Migration Steps

SharePoint data migration becomes more predictable when organizations prepare content before moving. A structured approach can reduce complexity and disruption.

These SharePoint migration best practices can help organizations prepare content, test the migration approach, and move workloads in controlled waves:

  • Prepare: Start by assessing the content and dependencies in your SharePoint Server 2016 environment. Inventory sites, libraries, lists, metadata, versions, permissions, workflows, applications, and integrations, then determine how each will be migrated, modernized, consolidated, archived, or retired in the target environment.
  • Pilot: Test your migration approach with a representative workload before moving large volumes of content. Include different content types, permission models, metadata, applications, workflows, and integrations, and have users complete real business tasks. Use the results to identify issues, refine your migration process, and confirm that content, access, functionality, and the target environment’s search experience work as expected.
  • Migrate: Move content in manageable waves based on business units, workload complexity, dependencies, criticality, or readiness. For each wave, confirm the scope and ownership, migrate the planned content, validate the results, communicate changes to users, and resolve issues before moving to the next wave. This phased approach gives teams greater control and helps limit business disruption.

How to Minimize Business Disruption During SharePoint Migration

Business continuity should remain central throughout the migration. Employees should not discover after migration that a critical document, application, workflow, or business process has changed unexpectedly.

  • Identify time-sensitive and business-critical workloads early and prioritize them based on their operational impact and dependencies.
  • Schedule migrations around business operations to minimize downtime and avoid disrupting critical activities. Communicate planned changes well in advance.
  • Prepare employees for the transition by explaining where they will find content, how access may change, which links or processes may be affected, and where to report issues.
  • Involve representative users in pilot testing and validation for critical workloads to identify usability and business-process issues that technical testing may miss.
  • Establish validation, contingency, and rollback procedures, where technically feasible, for high-impact workloads so teams can respond quickly if the migration does not meet business or technical requirements.

How to Validate and Stabilize Your SharePoint Migration

Technical migration reports can identify failed items and other errors, but technical completion does not necessarily mean the migration has succeeded. Business users must confirm that the new environment supports their work.

Validation should cover:

  • Data: Confirm that required content, metadata, and versions migrated accurately.
  • Access: Verify that users have the appropriate permissions and restricted information remains protected.
  • Functionality: Test applications, forms, workflows, and integrations.
  • Search: Confirm that users can find migrated information through the expected search experience.
  • Business operations: Have users complete representative tasks and confirm that critical processes work as expected.

Post-migration, allow time for stabilization. Monitor user issues, resolve exceptions, review access problems, and address unexpected behavior. Focus on improving information architecture, simplifying permissions, strengthening governance, optimizing search, and enhancing collaboration or automation.

Building a SharePoint Migration Strategy for Business Continuity

A successful SharePoint migration strategy requires coordinated planning across data, technology, users, and business processes. Organizations can reduce disruption by assessing their environment, preparing content, mapping dependencies, testing representative workloads, migrating in controlled waves, and validating each workload before moving forward.

The transition can also create a stronger foundation for Microsoft 365 and AI initiatives by improving information architecture, content quality, permissions, governance, and discoverability. Instead of simply reproducing the SharePoint Server 2016 structure, organizations can improve information organization, simplify access, retire unnecessary content, and create a better employee experience.

Synoptek provides SharePoint 2016 end-of-life migration services to help organizations plan and execute complex SharePoint transitions, including SharePoint data migration, migration planning, testing, validation, and phased implementation.

Book a Complimentary SharePoint Estate Assessment

Evaluate your current SharePoint environment, identify what to retain, modernize, archive, or retire, and determine the right path forward. Within 48 hours, receive an actionable roadmap to help plan your migration while minimizing disruption to critical business operations.

Book the Assessment

Why Generic Personalization Breaks Down for AI

BlogTell Me About Me: Why Generic Personalization No Longer Works

Read More

Executive Summary

  • Context dies at the click. Customers now give AI assistants detailed context before reaching your site, but that context never makes it to the page.
  • Visitors arrive convinced, not curious. A mismatched generic page doesn’t just fail to help; it can create doubt in an already-made decision.
  • Segmentation isn’t personalization. Broad buckets (“busy families”) no longer cut it when customers have already shared specific, individual context.
  • The fix is structural, not cosmetic. Static pages need to give way to modular content that assembles around the visitor’s actual question.

“I don’t care about busy families. I care about my family.”

That line came up during a recent panel hosted by Synoptek, where a small group of customer experience leaders sat down to take apart two real AI-driven buying journeys, live and unscripted. It wasn’t a planned soundbite. It was a reaction to watching someone shop for a family SUV using AI, then land on a car brand’s website, and get handed a generic “best cars for busy families” message instead of anything resembling the specific, detailed context they’d just spent five minutes giving an AI chatbot.

That gap is the whole story. And this is exactly why generic personalization no longer works.

The Context That Gets Left at the Door

Here’s the scenario the panel walked through. One of the panelists had a real conversation with an AI assistant about buying a family vehicle: two kids, one in travel soccer, a dog, a small garage, a strong preference for a hybrid, reliability over performance, and cargo space and total cost of ownership as top priorities. The AI took all of that in, reasoned through it, and recommended a specific model, then linked out to the brand’s website.

What loaded on the other end of that click had none of it. No hybrid preference. No cargo requirement. No mention of the small garage. Just the standard model page, gas trims front and center, the same experience every visitor gets regardless of what they told the AI thirty seconds earlier.

One panelist summed up what was lost in that jump bluntly: everything the visitor had just told the AI simply didn’t make the trip. Another framed it as a design problem: the website had been built assuming a visitor who arrives cold, browses, and self-selects their way toward relevant information. That assumption no longer holds when a visitor arrives already deep into a decision, carrying detailed customer context that never reaches the page.

The panel saw the same pattern play out in a second, unrelated scenario: a B2B buyer comparing CRM platforms who’d given an AI assistant a detailed brief on team size, integration needs, budget sensitivity, and implementation risk tolerance. The AI narrowed the field and linked to a vendor’s site. The page that loaded showed a free-tier offer, aimed at a much smaller company than the one being described. As one panelist put it, that mismatch doesn’t just fail to help; it can actively create doubt where none existed a moment before.

Why “Arriving Convinced” Changes Everything

There’s a subtler shift buried in these examples, and it’s the part that should worry marketing teams more than the missing context itself.

When someone arrives at a website after a traditional search, they’re usually still evaluating. They compare, they scan competitor tabs, they look for reasons to say yes. But when someone arrives after an AI conversation, they’ve often already decided. They’re not browsing anymore; they’re checking. The panel described this as arriving “convinced, not curious.” The visitor’s posture has flipped: instead of asking “prove to me this is good,” they’re unconsciously looking for anything that might prove their AI-informed choice wrong.

That means the website isn’t competing to win someone over anymore. It’s trying not to lose someone who already believes. And a page that responds with the same messaging it would give a total stranger, generic, undifferentiated, built for an average visitor who doesn’t exist, is exactly the kind of experience that plants unnecessary doubt.

Segmentation was Never Personalization

A recurring theme in the discussion was the difference between what most companies call personalization and what customers are increasingly starting to expect.

Traditional personalization usually means a name in a greeting line, or a handful of broad segments: “busy families,” “small business owners,” “budget-conscious shoppers.” One panelist pointed out that this kind of segmentation still assumes a lot of people fit neatly into one bucket, and then gives everyone in that bucket the identical experience. It’s a reasonable approximation when you don’t know anything about the individual in front of you. But AI conversations remove that excuse.

The visitor already handed over specific, individual customer context before they ever clicked through: their garage size, their sales team size, their actual budget constraints. Falling back to a broad segment after receiving that level of detail feels like a step backward, not an upgrade.

Real personalization, the panel argued, means recognizing the specific problem someone showed up with, not which demographic bucket they loosely resemble.

The Data was Already There; It Just Wasn’t Being Used

One panelist raised an important nuance here: none of this context is actually new information companies don’t have access to. Search engines, retailers, and platforms have quietly been assembling behavioral profiles on individuals for years; what people already search for, click, and buy shapes what they’re shown next, often without anyone consciously requesting it.

What’s changed with AI-powered search is that this customer context is now explicit, detailed, and handed over willingly, in the customer’s own words, as part of a real conversation. Someone typing “I lead revenue for a 500-person company, we’re evaluating CRM replacements; integration risk and implementation complexity matter more to me than every possible feature” isn’t leaving breadcrumbs to be inferred. They’re stating their priorities outright. The bar for using that information well is much higher than it used to be, because the excuse of “we didn’t know” no longer applies.

What Comes Next: Content Built Around the Question, not the Page

Perhaps the most interesting idea to come out of the discussion was a challenge to the very structure companies have relied on for two decades: the page itself.

One panelist suggested that the concept of a fixed “page”, a static, predetermined bundle of content, laid out the same way for every visitor, is itself a holdover from print media, not a requirement of the web. The alternative floated during the discussion was content built as smaller, modular pieces that get assembled dynamically around whatever specific question or context a visitor arrives with, rather than forcing every visitor through the same rigid structure regardless of what they already know or need.

That’s a meaningfully different model than “personalization” as most teams currently practice it, swapping a hero image or inserting a first name into an email subject line. It means rethinking how content gets structured at the source, so that it can be reassembled on demand around the actual problem a visitor showed up to solve.

A Quick Gut-Check for Your Own Site

If you’re wondering whether your own website falls into the generic-personalization trap, the panel’s discussion suggests a few honest questions worth asking:

  • If a visitor arrived having already told an AI assistant exactly what they need, would your homepage or product page look any different than it does for a first-time, context-free visitor?
  • Does your content assume everyone landing on a given page is at the same stage of their decision, or does it account for someone who’s already convinced and just checking your work?
  • When you talk about “personalization” internally, are you really describing individual recognition, or is it broad segmentation dressed up in nicer language?
  • Is your content structured as fixed pages built for browsing, or as modular pieces that could, in theory, be reassembled around a specific question?

None of these have easy or immediate fixes. But they’re the right starting questions, because they surface where the gap between what customers now expect and what most websites still deliver is widest.

Where this Leaves Marketing and CX Teams

None of this means personalization is impossible or that brands should panic. It means the bar has moved. Visitors now arrive with more context than ever, further along in their decision, and less patient with generic experiences that ignore what they’ve already said. Meeting that bar requires understanding not just who a segment is, but recognizing the specific problem an individual visitor brought with them, and building the flexibility to respond to it directly, rather than routing everyone through the same fixed path.

This is exactly the kind of shift Synoptek’s panel dug into using two real AI buyer journeys: a family car search and a B2B CRM evaluation, walking through what worked, what didn’t, and what a smarter response could have looked like at each step.

Want the Full, Unfiltered Conversation?

Watch the on-demand recording of the panel discussion, where customer experience leaders from Synoptek and outside brands take these examples apart in real time – no scripts, no talking points, just people who’ve done this work thinking it through together.

Watch the Full Discussion

SharePoint Online migration for a global manufacturer with Dynamics CRM integration

Case StudyManufacturer Advances Business Process Automation with SharePoint Online Migration

Read More
Customer: A Swiss firm specializing in reciprocating compressors Profile: A worldwide market leader for reciprocating compressor systems and the only manufacturer and service provider that covers a full range of reciprocating compressor technologies and services

Services: Microsoft Office 365/SharePoint Online, Microsoft Azure

Size:1001-5000 employees
Region: Zurich, Switzerland
Industry: Manufacturing

Business Need

The manufacturer provides leading technology and a broad portfolio of compressor components. Their full range of services helps customers find the optimized solution for reciprocating compressor systems, used in upstream oil and gas, refinery, chemical, industrial gas sectors, to minimize lifecycle costs, worldwide.

The manufacturer used SharePoint on-premises to manage multiple documents like quotes, cases, compressor details, visit reports, CRM emails, and notes. The SharePoint portal was integrated with Dynamics CRM, where any account created in CRM gets automatically updated in SharePoint. Various users located in USA, China, India, Switzerland and other European countries managed all their documents on the SharePoint portal. Gradually, the number of users reached over 10,000. As a result, the older version of SharePoint architecture became too clumsy and unpleasing in terms of performance, usability, and accessibility.

With the continuous increase in users and their data, the SharePoint portal that supported collaboration, file upload, task tracking, and content management, was becoming inefficient which caused it to run sluggishly and potentially fail more frequently. This led to higher cost and overall productivity issues.

In order to get an enterprise scalable solution to address the challenges faced by their end users, the manufacturer approached Synoptek, since we’ve provided expert-level SharePoint administration services to the client in the past.

Solution and Approach

Initially, Synoptek studied the manufacturer’s existing SharePoint architecture/farm and understood their requirements. Considering their pain areas and needs we planned to migrate their SharePoint on-premises portal to the cloud version i.e. SharePoint Online.

Starting with the pre-migration phase, we designed and developed the migration plan considering the governance information architecture as a reference. We also researched for some third-party migration tools for a secured and swift migration. However, since no such tool provided support for migration, Synoptek chose to design a migration tool. The tool was developed by applying 40+ customization rules using SCOM (System Centre Operations Manager), Client Side Object Model (CSOM), and PowerShell scripting.

The tool helped us:

  • Easily automate the process of consolidating 2TB of data to SharePoint Online.
  • Granularly migrate the content down to individual SharePoint items in real-time, or through dynamic scheduling.
  • Retain all associated metadata and permissions throughout the migration process.

Migration Process

The major challenge for Synoptek was to migrate a huge amount of data from the on-premises version to the cloud. The manufacturer was already using Symantec Vault, an enterprise application archive tool, for archiving huge number of files and documents to SharePoint Online.

Synoptek performed the following in the migration process: 1) Migration of archived documents from Symantec Vault to SharePoint Online, and 2) Incremental migration that migrates the added, modified, and/or failed data to the destination based on time.

Additional Customizations

Apart from migration, Synoptek also performed a few customizations on the new SharePoint Online Portal:

  • We redesigned the UI of SharePoint Online considering the best practices and the actual branding of the manufacturer. To get a better understanding of their needs, we performed detailed research and analysis during the initial phase of the project to understand the manufacturer’s business goals and end user challenges while using the existing on-premises version.
  • We enhanced the search functionality, where users can easily search for required files/documents across multiple sites. We also enabled proper filtration of information based on the configured criteria, making the search capability more appropriate.
  • We designed standard templates for files and documents that are uploaded on SharePoint Online.
  • Moreover, we developed a functionality called ‘Copy Tool’ where the user can create a copy of the master template of files/documents and can use for his own purpose. This will not affect or make any changes in the original template.

Tools and Technologies:

The migration process was planned, piloted, and coordinated using the following components:

  • SSOM
  • CSOM
  • PowerShell Script
  • Microsoft SQL
  • Windows application C#

We used PnP (Practices and Patterns) tool for performing complex provisioning related to site collection and site branding and later created similar sites. This reduced complexity and long term operational costs. In addition, the use of HTML 5, CSS 3.0, JavaScript, JS Framework, and REST APIs offered a better UI/ UX for SharePoint Online.

Dynamics CRM Online Integration

With CRM integration, the user encapsulates the document management capabilities of SharePoint from CRM. The documents can be stored and managed in the context of Dynamics CRM (now Dynamics 365 Customer Engagement) record on a SharePoint Server and leverage the SharePoint infrastructure to share, manage, and collaborate efficiently. Because the documents are stored on the SharePoint Server, the users can directly access the data with appropriate permissions. This integration of SharePoint with CRM helped to leverage the capabilities of advanced search functionality through the CRM document library as well.

All the user rights and permissions were retained during the migration and integration processes. For this we designed a user permission matrix that defines the permission rules based on the user type and his location. This matrix was designed considering the overall security of both SharePoint and Dynamics CRM systems.

Business Results

The migration to the Online version gives immediate access to an enhanced UI, better document collaboration and cutting-edge search and mobile responsive displays.

SharePoint Online has also reduced administrative costs related to ongoing maintenance by cutting down the cost of maintaining patches, repairing hardware, and security options.

With the migration of 2TB data and files to SharePoint Online, it became a go-to tool for both high volume migrations and day-to-day content management. This enables business continuity on the new platform by migrating all data with full reliability, including version history and all associated metadata. That allows for minimal interruption of end-user productivity.

Functionality and performance related issues were successfully addressed as they came up. This has resulted in high uptime of the system and reduced the resolution timescale. With the improved user experiences, compliance and reporting functionalities, migrating SharePoint on-premises to SharePoint Online proved out to be smart and logical business move.

By relying on Synoptek’s wide breadth of SharePoint knowledge, the client received a secured and mobile compatible architecture that was tailored to their business needs. compliance and reporting functionalities, migrating SharePoint on-premises to SharePoint Online proved out to be smart and logical business move. By relying on Synoptek’s wide breadth of SharePoint knowledge, the client received a secured and mobile compatible architecture that was tailored to their business needs.

A Practical Guide to Azure Cost Optimization: Tools, Best Practices & More

BlogCutting Cloud Waste: A Practical Guide to Azure Cost Optimization

Read More

Executive Summary

  • Azure costs quietly pile up through idle resources, oversized instances, and inconsistent tagging, not through any single bad decision.
  • Azure cost optimization best practices such as right-sizing, scheduled shutdowns, and disciplined tagging deliver the fastest and most reliable savings.
  • Native tools like Microsoft Cost Management and Azure Advisor cover the basics well; dedicated FinOps platforms add value as environments scale.
  • Lasting savings come from building an Azure FinOps culture with shared ownership, not from one-time cleanup projects that fade after a quarter.

Cloud bills rarely go down on their own. Teams spin up resources for a sprint, forget to decommission them, and three months later finance is asking hard questions about a line item nobody can fully explain. If that sounds familiar, you’re not alone. Azure cost optimization isn’t about slashing budgets or telling engineers to stop building. It’s about matching spend to actual value and doing it consistently enough that it becomes part of how your organization operates rather than a quarterly fire drill.

This guide walks through why cost optimization matters more than ever, Azure cost optimization best practices, Azure cost optimization tools that make the work manageable, and how to build an Azure FinOps culture that sticks long after the initial cleanup project ends.

Why Azure Cost Optimization Deserves a Seat at Your FinOps Table

Cloud spend has a way of becoming invisible. Unlike a server purchase that shows up as one big capital expense, Azure costs accrue quietly, resource by resource, region by region, until the monthly invoice arrives and surprises everyone. That invisibility is exactly why cost optimization needs a formal seat at the table rather than being treated as an occasional cleanup task.

Organizations that fold Azure cost optimization into their broader FinOps practice see the benefit compound over time.

  • Engineers start thinking about cost the same way they think about performance or security, as a design constraint, not an afterthought.
  • Finance gets predictable forecasts instead of end-of-month surprises.
  • Leadership gets the confidence to keep investing in cloud initiatives because the spend is transparent and justifiable.

The alternative, treating cost as someone else’s problem until the bill spikes, almost always costs more in the long run, both in wasted spend and in the friction it creates between engineering and finance teams.

The Real Cost of Ignoring Azure Cost Optimization Best Practices

Skipping cost discipline doesn’t just mean a higher bill; it changes how teams work. When nobody owns cost visibility, a few predictable things happen. Idle resources pile up because nobody’s job is to notice them. Oversized virtual machines become the default because it’s easier to overprovision than to right-size under deadline pressure. And when the annual budget review finally surfaces the total, the response is often a blunt, across-the-board spending freeze that slows down legitimate projects along with the wasteful ones.

Ignoring Azure cost optimization best practices also erodes trust between teams. Finance starts viewing every cloud request with suspicion. Engineering starts resenting budget conversations as bureaucratic overhead. Neither outcome helps the business move faster, which is usually the whole point of being in the cloud in the first place.

The fix isn’t a one-time audit. It’s a set of habits, applied consistently, that keep spend aligned with value as environments grow and change.

Right-sizing and Reservations: Core Azure Cost Optimization Best Practices

A handful of practices consistently deliver the biggest wins, and they’re worth mastering before chasing anything more exotic.

  • Right-size before you reserve. It’s tempting to jump straight to reserved instances or savings plans, but committing to the wrong size just locks in waste for one to three years. Start by matching compute, storage, and database tiers to actual utilization patterns, not to what seemed safe at launch.
  • Use reservations and savings plans deliberately. Once workloads are sized correctly, reserved capacity and savings plans can meaningfully reduce steady-state costs. The key is applying them only to workloads with predictable, long-term usage, not to every resource indiscriminately.
  • Shut down what isn’t running. Dev and test environments that sit idle overnight or over weekends are one of the most common sources of avoidable spend. Scheduled start and stop policies recover this cost with almost no engineering effort.
  • Tag everything, consistently. Cost visibility depends entirely on knowing which team, project, or environment a resource belongs to. Without a disciplined tagging policy, even the best analytics tools can’t tell you where money is actually going.
  • Set budgets and alerts before you need them. Waiting for the monthly invoice to catch a runaway resource is too slow. Budget alerts catch anomalies within hours instead of weeks.
  • Revisit storage tiers regularly. Data that was accessed daily at launch often goes cold within months. Moving infrequently accessed data to cooler storage tiers is low risk, high reward, and easy to automate.

Top Azure Cost Optimization Tools Worth Adding to Your Stack

Good habits go further with the right tooling behind them. A few categories of Azure cost optimization tools consistently pay for themselves.

  • Microsoft Cost Management + Billing is the natural starting point since it’s built into Azure and requires no additional licensing. It provides budgets, cost analysis, and recommendations that surface obvious waste, including idle VMs, underused disks, and orphaned public IPs, without any setup overhead.
  • Azure Advisor goes a step further by generating personalized recommendations across cost, reliability, security, and performance, drawing directly from your actual resource configuration and usage patterns. It’s especially useful for catching right-sizing opportunities that are easy to miss manually.
  • Third-party FinOps platforms, tools built specifically for multi-cloud cost governance, add capabilities native tooling doesn’t offer, like cross-cloud reporting, anomaly detection with machine learning, and chargeback or showback reporting that maps spend directly to business units. These are worth evaluating once an organization’s Azure footprint grows complex enough that native dashboards stop telling the full story.
  • Infrastructure-as-code cost estimators deserve a mention too, since they shift cost visibility left. Rather than discovering a poorly configured resource after it’s deployed, teams can see the projected cost impact of a Terraform or Bicep change before it ever merges.

The right combination depends on organizational maturity. Smaller teams often get most of the value from native Azure tooling alone; larger, multi-cloud organizations tend to layer in dedicated FinOps platforms once native reporting can’t keep pace with complexity.

Building an Azure FinOps Culture That Sticks

Tools and best practices only go so far without the organizational habits to sustain them. This is where Azure FinOps as a discipline, not just a toolset, comes in.

Azure FinOps works best as a shared responsibility model. Engineering owns the technical decisions that drive cost, including instance types, architecture patterns, and scaling policies. Finance owns forecasting and budget accountability. A central cloud or platform team owns tooling, tagging standards, and reporting. When these three groups meet regularly around shared cost data, spending conversations stop being adversarial and start being collaborative.

Cadence matters more than most teams expect. A weekly or biweekly review of cost anomalies, paired with a monthly deeper dive into trends and forecasts, keeps optimization proactive rather than reactive. Making cost data visible to engineering teams directly, rather than gatekeeping it behind finance, also tends to produce faster, more targeted fixes, since the people closest to a resource usually understand its usage pattern best.

Recognition helps too. Teams that hit cost efficiency targets alongside their performance and reliability goals are far more likely to keep optimizing than teams where cost is only ever raised as a criticism.

Common Pitfalls That Undermine Azure Cost Optimization Efforts

Even well-intentioned programs stumble in predictable ways.

  • One-time cleanups instead of ongoing processes. A quarterly cost sprint recovers some savings, but usage patterns drift again within weeks. Sustainable savings come from continuous monitoring, not periodic sweeps.
  • Over-indexing on reservations too early. Committing to long-term reserved capacity before workloads stabilize locks in guesses rather than facts and can cost more than on-demand pricing if usage patterns shift.
  • Treating cost optimization as purely a finance initiative. Without engineering buy-in, cost recommendations pile up unactioned. Cost needs to be an engineering metric, tracked alongside latency and error rates.
  • Ignoring architectural waste. Sometimes the biggest inefficiency isn’t an oversized VM; it’s an architecture that never needed that resource at all. Serverless or consumption-based alternatives can eliminate cost problems that right-sizing can only shrink.
  • No single source of truth. When multiple teams pull cost data from different dashboards with different assumptions, disagreements about the real number waste more time than the savings being debated.

Avoiding these pitfalls is less about sophistication and more about discipline, building the review habits and ownership structures that keep a good start from quietly unraveling.

Getting Started: A Practical Roadmap

For teams just beginning this work, a simple sequence tends to produce results fastest. Start by getting visibility: enable Cost Management, enforce tagging, and identify your biggest cost centers. Next, tackle the obvious waste, such as idle resources, oversized instances, and orphaned storage, since these wins build momentum and credibility for the broader initiative. Then formalize the cadence: recurring reviews, budget alerts, and clear ownership across engineering and finance. Finally, layer in commitment-based savings like reservations once usage patterns are stable enough to commit to with confidence.

For teams that want a more structured framework to build from, Synoptek’s white paper on Azure cloud cost optimization tips is a useful companion resource, covering why cloud overspend is so common and what a cost management program should include.

Turning Cost Optimization into a Competitive Advantage

Azure cost optimization isn’t a one-time project with a finish line. It’s an ongoing discipline that pays dividends as long as it’s maintained. Organizations that combine solid best practices, the right mix of tools, and a genuine FinOps culture don’t just spend less; they gain the confidence to invest more boldly in the initiatives that actually move the business forward, knowing their cloud spend is transparent, accountable, and aligned with real value.

The teams that get this right treat cost the same way they treat performance or security: as a shared responsibility, built into everyday decisions rather than bolted on after the fact.

Ready to Get Your Azure Spend Under Control?

Talk to a Synoptek cloud expert to assess your current environment and build a right-sized, cost-optimized Azure strategy.

Talk to a Cloud Expert